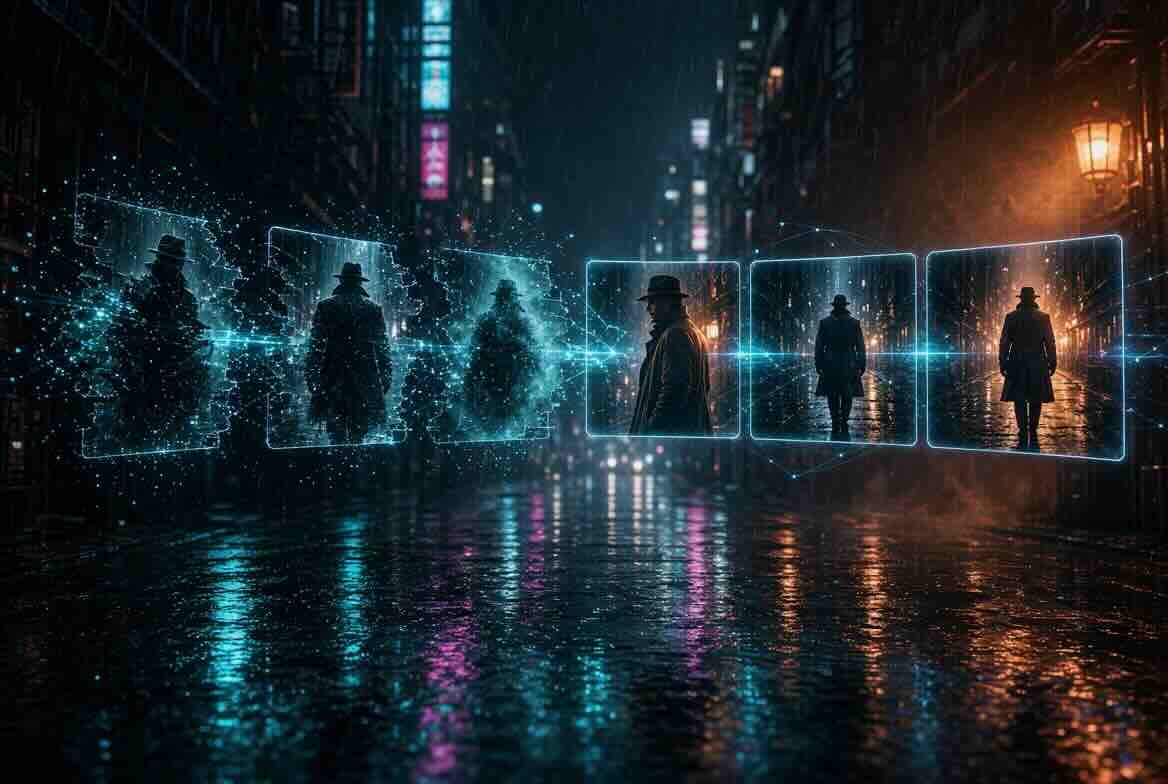
You generate a striking AI clip: a detective in a rain-slicked Tokyo alley, neon reflections pooling on wet pavement, the camera tracking him with a slow push-in. It looks cinematic. Then you generate the next shot — the close-up of him discovering a strange object. The face is almost the same person, but the jawline has shifted. The lighting is warmer. The alley geometry no longer matches. Each clip works on its own. Together they feel like two different films.
Making one impressive clip is getting easier. Making several of them feel like they belong to the same movie is getting harder — and it matters more.
The real shift in generative AI video isn’t better individual clips. It’s better control over the relationships between clips: continuity, cinematography, sequencing, keeping characters and environments consistent, lighting logic, temporal coherence, and the planning that holds it all together.
What generative AI video actually is
These systems turn text prompts, still images, existing video, or some mix of references into moving images. The main modes:
- Text-to-video — a written description becomes a clip
- Image-to-video — a still gets animated or extended into motion
- Video-to-video — an existing clip gets restyled, extended, or transformed
- Reference-driven generation — images, clips, or other assets guide identity, style, or motion
- Video extension — continuing an existing generation while trying to preserve continuity
- AI-assisted editing — tools that regenerate, inpaint, or refine segments inside a larger workflow
Image generation produces a single coherent frame. Video has to produce a sequence of frames that stay coherent over time. That’s the hard part. The model has to keep spatial relationships, object identities, lighting, approximations of physics, and camera motion stable across dozens or hundreds of frames. Small errors compound. A slight shift in face shape or light direction that you’d never notice in a still becomes obvious the moment the sequence plays.
Free tool
AI Video Sequence Builder
Generating one good clip is easy. Getting six of them to look like the same film is the hard part. This builder sits between your story idea and your generator, so every shot inherits the same character, environment, and lighting before you spend a single credit.
- Lock — character, environment, and lighting described once, inherited by every shot.
- Build — up to six connected shots, each with lens, camera movement, action, and duration.
- Direct — explicit cinematic parameters instead of vague prose.
- Check — flags continuity breaks, aggressive movement/duration combos, and abrupt focal-length jumps.
- Export — structured prompts or timeline data for Runway Gen-4, Kling 3, Veo 3.1, Seedance, and related models.
Works with Runway Gen-4 · Kling 3 · Veo 3.1 · Seedance
Open the Sequence Builder →How it works, roughly
A prompt or reference goes in. The model interprets the scene, subjects, action, and style. It generates visual information while trying to preserve temporal and spatial relationships. Out comes a clip, sometimes with synchronized audio.
The practical difficulties show up fast. Temporal consistency means the same person or object stays recognizable frame to frame. Spatial consistency keeps positions and scale stable. Character consistency preserves facial identity, wardrobe, proportions. Object and environment consistency stops props and backgrounds from drifting. Physics approximations — water, fabric, collisions, weight — still break in complex cases. Camera movement has to feel intentional rather than arbitrary. And scene continuity across cuts remains the biggest open problem for multi-shot work.
A single beautiful generation can still fail as part of a story if the next shot breaks any of those relationships. Which is why the industry’s attention has moved from isolated clip quality toward the mechanisms that link clips together.
The trends worth watching
1. Clips are becoming sequences. The early pattern was prompt, clip, done. The emerging pattern is story, sequence, shots, generation, editing. Creators increasingly treat generation as one stage inside a larger cinematic process. Tools that support multi-shot direction, shared visual context, and continuity checks are rising in importance, precisely because isolated excellence is no longer the bottleneck.
2. Character consistency is table stakes. A visually strong clip still fails narratively if the protagonist’s face, hair, or clothing changes between shots. Identity preservation, wardrobe locking, facial consistency — these are now core requirements. Character drift, the gradual or sudden alteration of a subject, remains one of the most common failure modes. Reference images, subject libraries, and locked descriptions are the practical countermeasures. A beautiful generation that can’t be matched to the previous shot is often just unusable.
3. Environment and lighting continuity matter more than people expect. Locations, weather, time of day, color temperature, atmosphere — all of it has to hold logical relationships across cuts. A character walking from a rainy neon alley into a suddenly dry, differently lit version of the same alley breaks immersion. Lighting logic and environmental anchors are becoming as important as the subject itself. Locking these before generation cuts down on wasteful regeneration.
4. References are becoming control mechanisms. Not guarantees, mind you. Creators use them to establish characters, objects, environments, and visual identity. Many current systems take multiple reference images, or combinations of image, video, and audio. The point is to constrain the generation space so the model is less free to invent inconsistent details. Results still need inspection and iteration.
5. Prompting is starting to look like shot direction. “A man walks through a city” is giving way to structured direction: subject, action, framing, lens, camera movement, lighting, duration, emotional intent. Models respond better when the language mirrors how filmmakers describe shots.
6. Camera movement is becoming a creative control. Explicit control is replacing prompt-based hope. Dolly in builds tension or discovery. Dolly out reveals space or isolation. Tracking follows action. Orbit shows character in relation to environment. Pan or whip pan redirects attention. Static wide establishes geography. The storytelling purpose of the move matters more than the technical label.
7. It’s becoming a pre-production problem. Traditional filmmaking goes script, storyboard, shot list, production, editing. The emerging AI workflow looks similar: idea, storyboard or sequence plan, character/environment/lighting lock, shot planning, generation, editing. Better models don’t eliminate planning. If anything, they raise the cost of poor planning, because regeneration still burns time and credits.
8. Model-agnostic workflows are winning. Creators now have several strong generators to choose from — Runway Gen-4.5, Google Veo 3.1, Kling 3.0 and early 4.0, Seedance 2.0/2.5, and others. The practical question is shifting from “which model makes my whole piece?” to “which model is best for this specific shot?” Workflows that sit above any single model, locking visual context and exporting structured direction, are getting more valuable.
9. Generation and editing are converging. Generation is increasingly treated as part of a timeline-based, iterative process. Tools support regenerating segments, performance transfer, inpainting, camera control after the fact, structured shot information. The line between “generate” and “edit” is blurring. Research systems like Google’s multi-agent frameworks — Co-Director, CANVAS and related components — explicitly target long-form coherence by planning, tracking world state, and refining across shots.
Sora vs. Runway, for what it’s worth
OpenAI’s Sora 2 launched in September 2025 with strong physics-aware motion, synchronized audio, multi-shot capability within generations, and improved controllability. The consumer product and apps were discontinued in April 2026, and the API ended in September 2026. So it’s a historical reference now, not a current option.
Runway’s current flagship line is Gen-4 / Gen-4.5, after the Gen-3 family was retired in mid-2026. Gen-4 emphasized reference-driven consistency for characters, objects, and locations. Gen-4.5 added stronger text-to-video, motion quality, and prompt adherence, all inside a broader platform with camera controls, performance capture (Act-One / Act-Two), and editing tools.
| Capability | Sora 2 (historical) | Runway Gen-4 / Gen-4.5 |
|---|---|---|
| Text-to-video | Strong | Strong (especially Gen-4.5) |
| Image-to-video | Supported | Core strength, reference-driven |
| Reference workflows | Image and limited multi-shot | Multiple references, world consistency focus |
| Camera control | Prompt + some multi-shot direction | Explicit controls + motion tools |
| Character consistency | Improved within generations | Reference anchoring across shots |
| Scene continuity | Multi-shot within single generation | Stronger via references and platform tools |
| Creative controls | Physics, audio, storyboarding features | Motion, performance capture, editing suite |
| Editing workflow | In-app tools while available | Integrated generation + post tools |
| Multi-shot workflows | Supported within generations | Platform supports sequencing and iteration |
| Best use cases (then/now) | Cinematic clips with audio and physics | Directed production shots and iterative control |
The more useful question isn’t which model wins. It’s which workflow gives the creator the control the project needs. A model that produces beautiful isolated clips is less valuable than one — or a combination of models — that can be directed toward coherent sequences.
Best generators, by use case
This changes quickly. As of late 2026, practical recommendations by use case rather than absolute ranking:
- Cinematic storytelling and realism with native audio: Google Veo 3.1 — strong physics, prompt adherence, synchronized dialogue/SFX/ambience, up to 8-second generations that can be extended, 4K options.
- Creative production workflows and directed control: Runway Gen-4.5 — reference consistency, camera tools, performance capture, editing integration.
- Multi-shot sequences and longer single generations: Kling 3.0 (multi-shot storyboarding up to roughly 6 shots / 15 seconds) and early Kling 4.0 (up to 30 seconds, richer references); Seedance 2.5 (up to 30 seconds, large multimodal reference sets).
- Reference-driven consistency and multimodal input: Seedance 2.0/2.5 — dozens of image, video, and audio references possible.
- Experimentation and rapid iteration: faster/turbo variants across platforms, lower-cost tiers.
- Model-agnostic sequence planning: tools that lock context and export structured direction for multiple generators.
No single model is best for every shot. Most serious creators already route different shots to different systems.
Why consistency is still hard
Character drift, object drift, inconsistent environments, lighting shifts, physics errors, camera discontinuity, temporal instability, complex multi-subject interactions, long-form coherence. These remain real limitations. Stronger models reduce how often and how badly they show up. They don’t remove the need for creative direction, reference locking, inspection, and selective regeneration. Being honest about the limits is part of the job.
Planning a multi-shot AI video
- Define the story. What happens, and why does it matter?
- Define the main character. Who is the subject, and what has to stay constant?
- Lock the character. Face, hair, wardrobe, build, distinguishing details.
- Lock the environment. Location, weather, architecture, props that persist.
- Lock lighting. Time of day, color temperature, key sources, atmosphere.
- Create the shot list. What happens in each shot, and how it advances the story.
- Choose camera and lens. What the viewer needs to see, at what scale.
- Define movement. How the camera moves, and why.
- Define duration. How much time the action needs.
- Check continuity. Does every shot logically follow the last in space, time, lighting, and character state?
A six-shot example
Scenario: a detective discovers a mysterious object in a rainy Tokyo alley.
- Shot 1 — Establishing. 24 mm, wide, slow tracking, 4 seconds. Establishes the rainy neon alley and places the character in space.
- Shot 2 — Follow. 35 mm, tracking, 4 seconds. Moves with the detective through the environment, same lighting and weather.
- Shot 3 — Discovery. 85 mm, dolly in, 3 seconds. Reveals the object, tension rising.
- Shot 4 — Reaction. 50 mm, gentle orbit, 4 seconds. Shows the character’s face and emotional response, identity locked.
- Shot 5 — Action. 50 mm, lateral movement, 4 seconds. Advances the story as the detective interacts with or reacts to the object.
- Shot 6 — Reveal. 24 mm, dolly out, 5 seconds. Pulls back to a wider view that recontextualizes the discovery.
The exact lenses, moves, and timings are adjustable. The practice is what matters: treating each shot as part of a planned sequence, not an isolated prompt.
Clip-first vs. sequence-first
Workflow A (clip-first): prompt, generate, prompt again, generate, prompt again, generate, edit, discover continuity problems, regenerate.
Workflow B (sequence-first): story, character lock, environment lock, lighting lock, shot planning, sequence continuity check, generation, editing.
The second approach doesn’t guarantee perfect output. It reduces unnecessary regeneration, surfaces continuity problems before credits get spent, and gives the creator more intentional control over the final piece.
Where a sequence builder fits
A sequence builder sits between the story idea and the video-generation model. It doesn’t replace the generator. It prepares coherent direction for it.
One example is the free AI Video Sequence Builder at The Right GPT (https://therightgpt.com/ai-video-sequence-builder/). The workflow:
- Lock — character, environment, and lighting described once, so every shot inherits the same context
- Build — up to six connected shots, each with lens, camera movement, action, duration
- Direct — explicit cinematic parameters instead of vague prose
- Check — diagnostic review for continuity issues, aggressive movement/duration combos, abrupt focal-length jumps, sequence logic problems
- Export — structured prompts or timeline data for supported generators (currently Runway Gen-4, Kling 3, Veo 3.1, Seedance, and related models)
The value isn’t that one tool solves consistency. It’s that planning and locking visual context before generation is becoming a necessary part of professional AI video work. Whether you use a dedicated sequence builder, a spreadsheet, or careful manual prompt management, the underlying discipline is the same. Treat AI video as cinematic sequencing, not isolated clip generation.
The next stage of generative AI video isn’t prettier frames. It’s the ability to direct coherent multi-shot sequences with control over character, environment, lighting, camera, and narrative flow. Creators who adapt their workflows to that reality will get stronger results with less wasted effort.